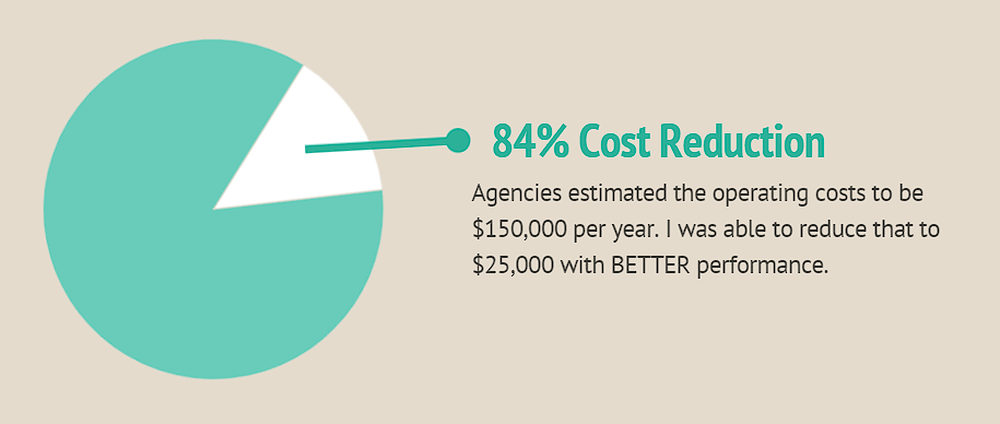
When extracting data from a 3rd party source, the methods used heavily rely on the conditions of where the data is coming from. Each request for data could take several seconds. This presents a big problem when the project requirements include a quarter of a billion requests per day.To make this happen sequentially, 250 million requests at 2 seconds per response - that would take almost 16 years to complete! The data sources were taking up to 5 seconds. And I had to make it happen within a 24 hour period...Two agencies said it can't be done, and the others who said it's possible were quoting $150,000 per year in operating costs.
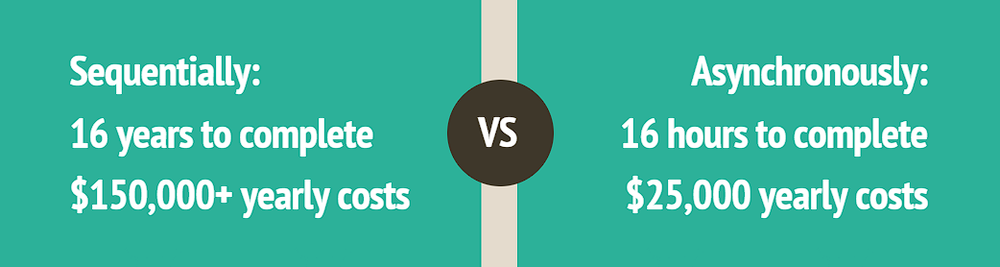
Through an orchestration of asynchronous and multi-threaded programming, a network of queues and progress tracking databases, and minimal yet effective set of AWS resources, I was not only able to make the 250 million requests in less than 16 hours but doing so with a reduction of expenses by 84%!I was able to achieve this by maximizing the tuning between the threads and asynchronous workers eliminating even the smallest of bottlenecks. This effect trickled down. Because the goal was achieved in less than the 24 hour requirement, the client was able to shut down a bulk of the resources for the rest of the day. Additionally, I was able to eliminate other resources entirely (like Lambda) through effective code.